TL;DR
- Most organizations dramatically underestimate how long the pilot-to-production journey takes — and consistently misdiagnose why it takes that long.
- Technical build time is rarely the bottleneck. Data readiness, stakeholder alignment, governance setup, and change management account for the majority of delays.
- The organizations that move fastest are not the ones with the best models. They are the ones that treat production requirements as preconditions for the pilot, not as problems to solve after it succeeds.
Introduction
Ask an organization how long it expects its AI pilot to take from kickoff to production, and most will say three months. Ask the same organization twelve months later how the rollout is going, and the answer is almost always the same: still in pilot.
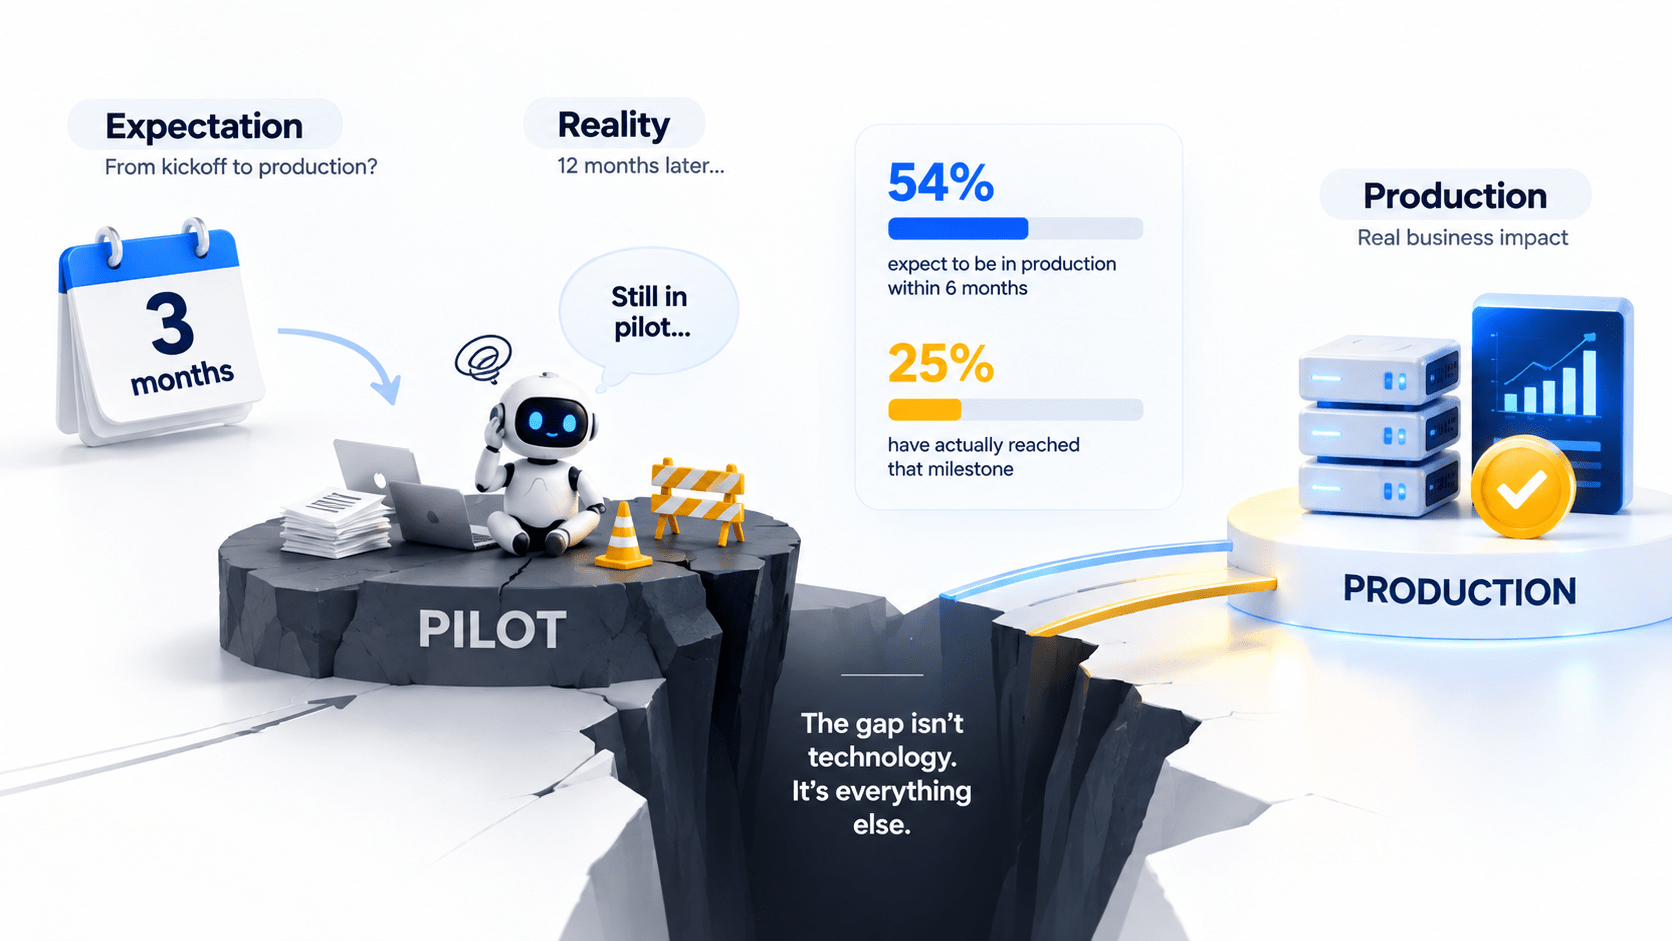
The gap between expectation and reality in AI deployment timelines is not new, but it has become more consequential as enterprise AI investment has scaled. According to Deloitte’s 2026 State of AI in the Enterprise report, 54% of organizations expect to have the majority of their AI initiatives in production within six months – while only 25% have actually reached that milestone. The gap between aspiration and reality is not driven by technology limitations. It is driven by a consistent failure to account for everything that makes a pilot a production system rather than a demo that works under controlled conditions.
This article maps the realistic timeline for moving an AI workflow from pilot to production — phase by phase, including the non-technical delays that standard project plans do not budget for — and explains what distinguishes the organizations that actually get there from the majority that remain stuck in what practitioners have started calling “pilot purgatory.”
Why the Timeline Is Almost Always Longer Than Planned
Before mapping the phases, it is worth understanding why estimates are consistently wrong — and why they tend to be wrong in the same direction and for the same reasons across organizations of different sizes, industries, and technical maturity levels.
The core issue is that pilots and production systems are fundamentally different things, and organizations treat the transition between them as a technical deployment step rather than an organizational transformation. AvePoint’s State of AI 2026 Report found that 87% of organizations delayed AI deployments because data security and data management risks made production rollout too difficult to justify — not because the model was not ready, but because the governance infrastructure around it was not. The pilot demonstrated that the AI could perform the task. It did not demonstrate that the organization was ready to let it perform that task at scale, with real data, under real operational conditions.
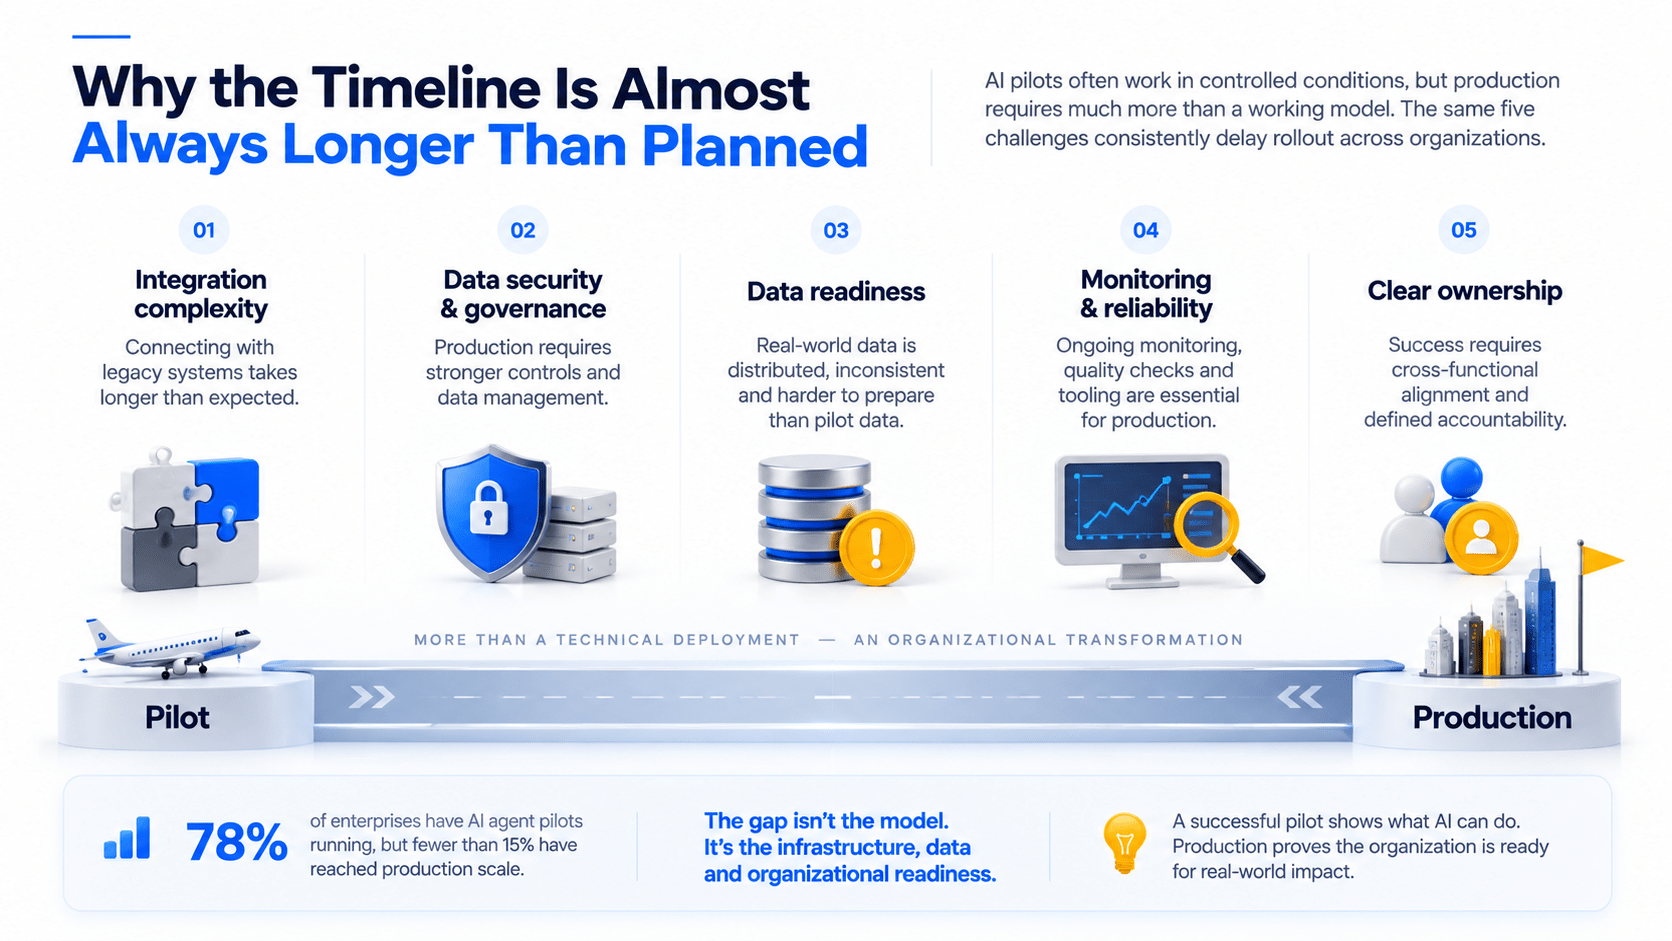
A March 2026 survey of 650 enterprise technology leaders found that 78% of enterprises have AI agent pilots running, but fewer than 15% have reached production scale. Five gaps account for the vast majority of scaling failures: integration complexity with legacy systems, inconsistent output quality at volume, absence of monitoring tooling, unclear organizational ownership, and insufficient domain training data. None of these are model problems. All of them are infrastructure and organizational problems that pilots routinely defer until after the pilot has been declared a success — at which point they become the reason the production rollout stalls.
The second reason estimates are wrong is that data readiness is almost always discovered as a problem after commitment rather than before it. Gartner’s research projects that 60% of AI projects lacking AI-ready data will be abandoned — and according to a March 2026 survey by Cloudera and Harvard Business Review Analytic Services covering more than 1,500 enterprise IT leaders, only 7% of organizations say their data is completely ready for AI adoption today. The pilot ran on curated, clean, bounded data that someone prepared specifically for the test. Production runs on the actual data the organization has — which is distributed across multiple systems, inconsistently formatted, partially governed, and in most cases structurally different from what the pilot was built on.
The Realistic Phase-by-Phase Timeline
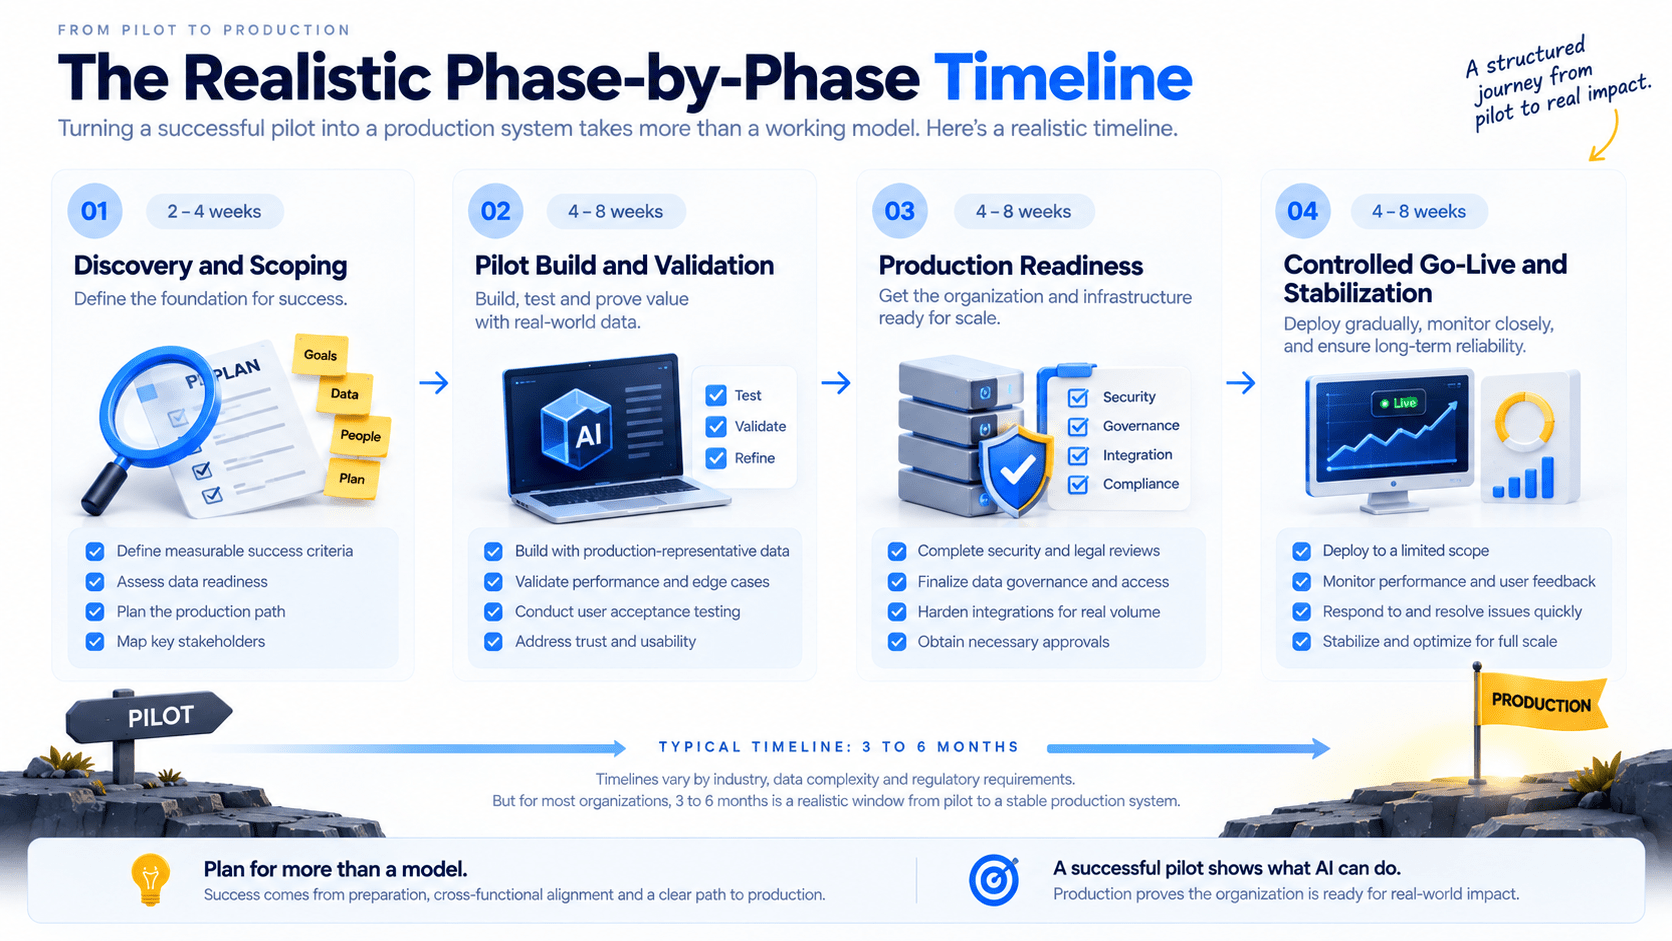
Phase 1: Discovery and Scoping — 2 to 4 Weeks
The discovery phase is where most timeline overruns are seeded, because it is also the phase most frequently compressed or skipped entirely in the rush to demonstrate early AI capability. Organizations under pressure to show AI progress move quickly to building a demo. The demo works. Stakeholders are impressed. The pilot is approved. The discovery work that would have revealed the data gaps, the integration complexity, and the governance requirements that will later stall the production rollout never happens.
Done properly, discovery covers four things that no later phase can substitute for. First, a clear and measurable definition of what success in production looks like — not “the AI performs well” but a specific metric, a specific threshold, and a specific measurement method that the economic buyer has agreed to in writing before the pilot starts. Research on AI pilot failure identifies the absence of pre-agreed success metrics as one of the most reliable predictors of pilot stall: if success can be contested after the fact by a stakeholder who was not aligned upfront, the pilot will fail even if the numbers are good.
Second, an honest data readiness assessment that maps what data the production workflow will depend on, where that data lives, what format it is in, who owns it, and whether it can be accessed at the volume and frequency production will require. This assessment should happen before the pilot build starts, not after it succeeds. Third, a production path definition — the engineering resources, data contracts, budget, and timeline that will be required to take the pilot to production if it delivers. Data from enterprise AI deployments suggests that 61% of pilots are approved with no plan for what happens if they succeed. The production bottleneck arrives as a surprise because nobody planned for the pilot working.
Fourth, a stakeholder map identifying who must approve the production deployment, what their specific concerns are, and what evidence each will require before they will authorize go-live. Stakeholder alignment failures are one of the most common causes of pilot purgatory — technically successful pilots that cannot move to production because a security team, a legal function, or a business unit leader was not engaged during the pilot and raises blocking objections when production deployment is proposed.
Phase 2: Pilot Build and Validation — 4 to 8 Weeks
With clear success criteria, a data readiness baseline, and a production path defined, the technical build phase is actually the most predictable part of the timeline. The uncertainty in the pilot build is not primarily technical — it is in the degree to which the data available for the pilot reflects the data production will use. Pilots built on representative production data with realistic integration conditions validate more quickly and translate more cleanly to production than pilots built on curated samples under controlled conditions.
AI pilot validation should be tested against real data from operational archives rather than synthetic or hand-curated test sets. The failure modes that appear in production but not in testing — distribution shift, silent quality degradation, context loss, integration instability — are structurally harder to detect when the test environment is cleaner and more orderly than the production environment will be. A pilot that validates successfully against realistic production-representative data is a pilot that is actually ready for the next phase. A pilot that validates successfully against curated demo data is a demo, regardless of how it was labeled.
User acceptance testing in this phase should also cover trust and usability, not just technical function. Research on enterprise AI adoption consistently finds that technically functional AI systems fail in production for non-technical reasons — users who do not trust the outputs, reviewers who do not understand the escalation logic, operations teams who work around the system rather than through it because the interface does not communicate what the system is doing clearly enough to be actionable. UAT that surfaces these issues during the pilot phase is significantly cheaper to address than UAT that surfaces them after production deployment has begun.
Phase 3: Production Readiness — 4 to 8 Weeks
Production readiness is the phase that most timeline estimates omit entirely, and it is where the majority of pilot purgatory cases actually get stuck. The pilot has succeeded. The results look good. The project team wants to go live. And then the organization discovers that going live requires things nobody budgeted time for: security reviews, procurement approvals, IT infrastructure provisioning, data governance sign-offs, legal review of AI decision-making in the relevant operational context, and HR or change management processes for the teams whose workflows the AI is entering.
Each of these has its own timeline, its own approval chain, and its own criteria for what “ready” means. A security review for a system processing sensitive business data in a regulated industry can take four to six weeks independently of how ready the AI system itself is. A data governance sign-off that requires mapping every data point the system accesses to its classification and ownership record takes time proportional to how well the organization’s data governance documentation already exists — which in most cases is less well than anticipated.
This phase also includes integration hardening — moving from the controlled integration the pilot ran on to the production integration that must handle real volume, real failure modes, and real operational conditions. API connections that worked reliably in a low-volume pilot environment may behave differently under production load. Data feeds that were stable during the pilot may have update schedules, access controls, or schema variations that the production workflow must handle. Integration hardening catches these issues before they appear as production failures. Skipping it because the pilot integration “worked fine” is one of the most common sources of production incidents in the first weeks after go-live.
Phase 4: Controlled Go-Live and Stabilization — 4 to 8 Weeks
A controlled go-live — deploying to a subset of users, a subset of cases, or a subset of the intended workflow scope — is the difference between a production deployment that can be corrected quickly when issues surface and one that has already distributed its failure mode across the full operational scope before anyone identified it.
The stabilization period covers the gap between “the system is running in production” and “the system is performing reliably at production scale.” Research on AI model monitoring shows that production performance metrics routinely diverge from pilot baselines within the first four to eight weeks of go-live — not because the system has malfunctioned, but because production inputs are more variable than pilot inputs, production integrations are more complex than pilot integrations, and production users interact with the system in ways the pilot did not anticipate.
Stabilization requires active monitoring, rapid response to metric deviations, and a clear protocol for what happens when a monitored metric breaches its baseline — who gets the alert, what they are expected to do with it, and what decision authority they have to adjust the system’s configuration or escalation thresholds in response. Organizations that do not establish this protocol before go-live spend the stabilization period improvising responses to issues they should have planned for.
The Non-Technical Delays Nobody Plans For
Data Readiness Gaps Discovered Mid-Build
Data readiness is almost always discovered as a problem after the pilot build has started rather than before it. The discovery phase assessment identified that the required data exists. What it did not identify — because it required going deeper into the actual data than a scoping exercise typically goes — is that the data exists in three different systems with incompatible schemas, that the most recent records are twelve months old because the relevant process changed and nobody updated the feed, or that the field the workflow depends on is populated inconsistently and requires cleaning before it can be used reliably.
When data readiness gaps are discovered mid-build, the pilot timeline extends by however long it takes to resolve them — which is typically not the two weeks the team optimistically estimates when the gap is first identified, but the four to eight weeks that systematic data cleaning, schema reconciliation, and feed reconfiguration actually require. Gartner estimates that 85% of AI projects fail because of poor data quality. The more precise version is that they fail because data quality problems are treated as inputs to be assembled during the pilot rather than preconditions that must be verified before it begins.
Stakeholder Misalignment at the Production Gate
The stakeholder who approved the pilot budget is not necessarily the stakeholder who must approve the production deployment. Security teams, legal functions, data privacy officers, and business unit leaders whose workflows the AI is entering may have had no visibility into the pilot and will surface blocking objections when production deployment is proposed — not because they oppose AI adoption, but because they were never engaged in defining what responsible deployment looks like for their specific domain.
Each unengaged stakeholder adds a review cycle to the production gate. Each review cycle has its own timeline, its own information requirements, and its own criteria for what it needs to see before it will approve. Stakeholder misalignment at the production gate is the single most common cause of the gap between “pilot complete” and “production deployed” extending from weeks to months.
Change Management Debt
The Google Cloud DORA 2025 report attributes 70% of AI transformation value to people, organizations, and processes — not to the technology itself. Yet Deloitte’s 2026 State of AI survey of more than 3,000 senior leaders found that only 37% of organizations had invested significantly in change management alongside AI deployments. The result is that technically successful pilots deploy into organizations where the people expected to use them have not been prepared to trust or work with them effectively — and where the workflows the AI is entering have not been redesigned to accommodate what the AI actually does well versus what it requires human judgment for.
Change management debt accumulates when AI deployment is treated as a technology project rather than an operational change. The cost of that debt is not paid during the pilot — it is paid during stabilization, when user adoption is lower than projected, when the system is being worked around rather than through, and when the operational efficiency gains the business case predicted are not materializing because the organizational conditions required to realize them were never created.
What Separates Organizations That Get to Production From Those That Don’t
The organizations that successfully move from pilot to production are not those with the most sophisticated models, the largest AI budgets, or the most technically ambitious pilots. According to research on enterprise AI scaling, successful scalers invest a significantly higher proportion of their AI budget on foundations — data infrastructure, governance, integration architecture, and change management — compared to organizations whose pilots stall. The technology investment is smaller relative to total spend. The infrastructure investment is larger. The result is a production deployment that actually performs rather than a technically impressive pilot that cannot survive contact with real operational conditions.
Three practices distinguish successful deployments consistently. They define production requirements before the pilot starts, not after it succeeds. They treat data readiness as a precondition rather than an input. And they engage every stakeholder who will touch the production approval gate during the pilot phase, not after it completes.
The timeline implications of these practices are counterintuitive. Organizations that do the foundational work upfront — the discovery, the data assessment, the stakeholder engagement — appear to be moving more slowly during the pilot phase. In practice, they are removing the blockers that will stall every other organization at the production gate. Their production conversion rate is higher, their stabilization period is shorter, and their time from first production deployment to measurable business impact is consistently lower than organizations that optimized for a fast pilot at the expense of a reliable production path.
How NORA Gets to Production in 6 to 8 Weeks
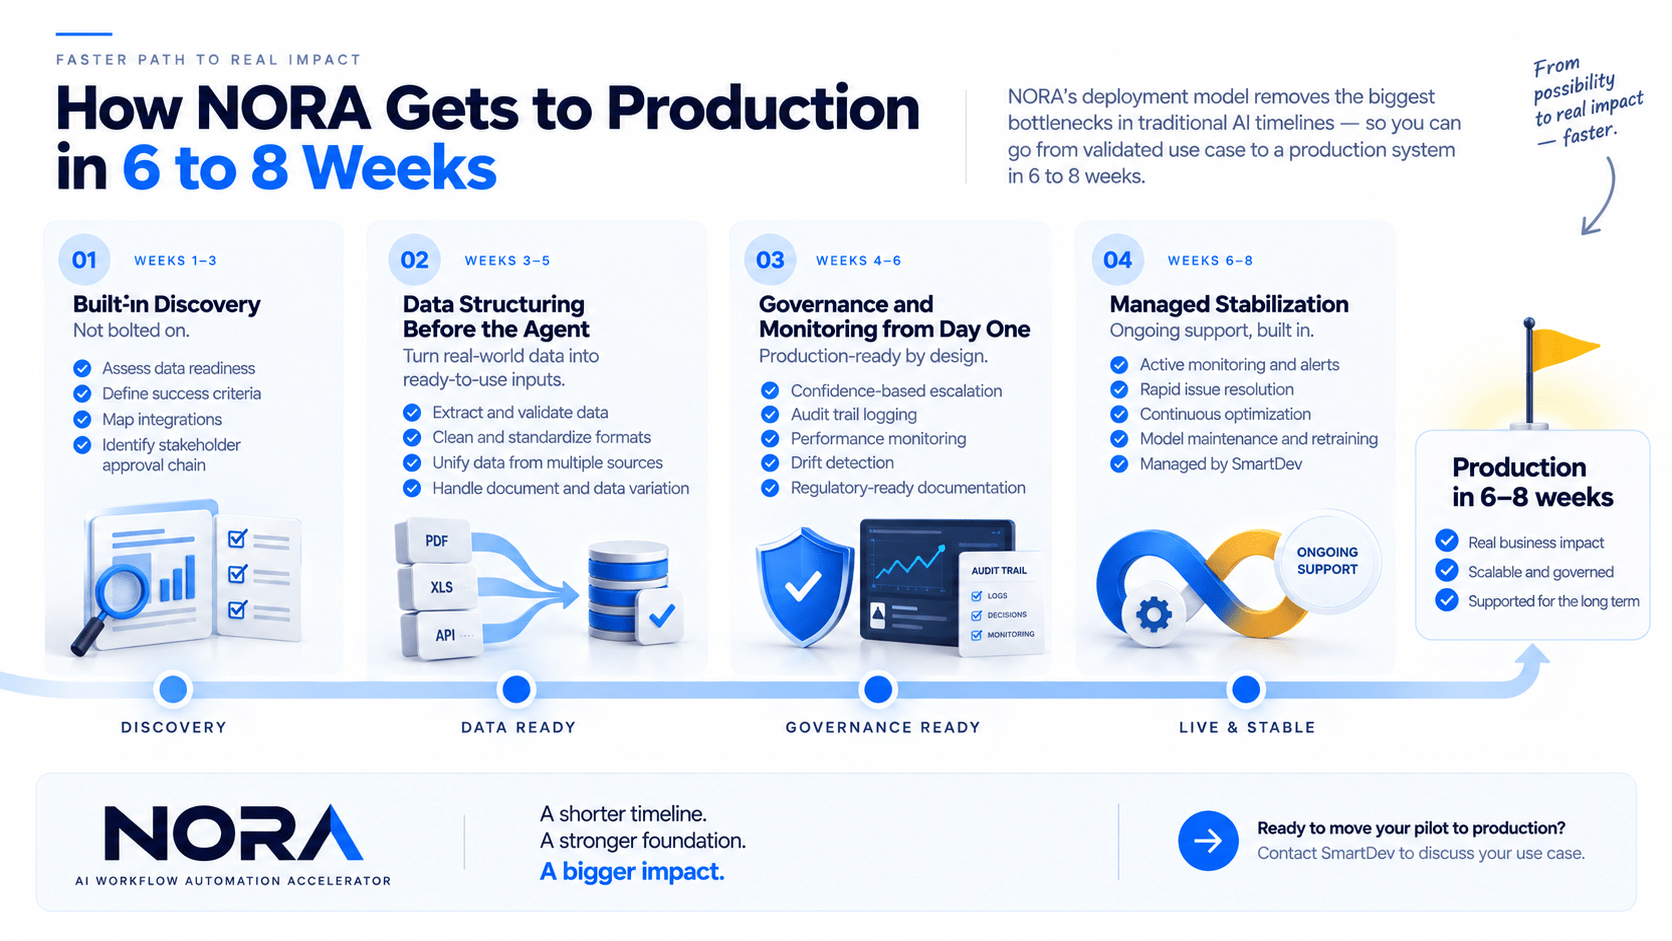
The average enterprise AI timeline described above assumes an organization building and deploying its own AI workflow infrastructure from scratch — with all the data readiness work, integration complexity, governance setup, and change management investment that entails. NORA’s deployment model is designed to compress that timeline by removing the categories of work that most commonly cause it to extend.
Discovery Is Built Into the Engagement, Not Bolted On
Every NORA deployment begins with a structured discovery phase that establishes data baselines, defines acceptance criteria, maps integration requirements, and identifies the stakeholder approval chain before any configuration work starts. The 3-Week AI Discovery Program produces a documented readiness assessment and a clear production path specification before the build begins — so the data gaps, integration complexity, and governance requirements that typically surface as surprises mid-build are identified and scoped upfront.
This is not a longer discovery phase that delays the pilot. It is a discovery phase that makes the subsequent build predictable by removing the unknowns that cause it to extend. Organizations that enter the NORA build phase with a clear data baseline, defined acceptance criteria, and a mapped integration architecture complete the build faster and with fewer mid-build course corrections than those who begin configuring without that foundation.
Data Structuring Before the Agent Sees Production Inputs
One of the most common causes of pilot-to-production timeline extension is the discovery that production data is messier, more inconsistent, and less structured than the data the pilot was built on. NORA’s Foundation Data Skills — Information Extraction, Data Screening, and Unified Data Indexing — address this by processing and structuring incoming data before it reaches the agent layer. Production inputs are converted into consistent, validated formats that the agent can process reliably regardless of the variation in source documents and data feeds.
This data layer compresses the data readiness work that typically extends the production readiness phase, because the production integration does not require the client’s data to be pre-cleaned and pre-structured. The NORA data layer handles that structuring as a continuous operational function, which means the production deployment is not dependent on a data quality state that the organization needs to reach before go-live — it is compatible with the data quality state the organization actually has.
Governance and Monitoring From Day One
The production readiness delays caused by absent monitoring infrastructure, undefined escalation protocols, and governance documentation that does not exist are removed from the NORA timeline because these elements are built into the deployment rather than added after. Confidence-based escalation routing, audit trail logging, performance baseline monitoring, and drift detection are configured during the build phase and active from the first day of go-live — not added as a later phase after the first production incident reveals that they were missing.
The governance record that security reviews, data privacy assessments, and regulatory auditors require exists as a structural output of the NORA deployment process. The escalation protocol is defined and tested before go-live. The stakeholder approval chain is engaged during the discovery phase. The result is a production gate that opens because the required evidence already exists, rather than one that stalls because assembling that evidence is a separate workstream that nobody budgeted time for.
Managed Service Means Stabilization Is Covered
The stabilization period that follows most production deployments — the four to eight weeks of active monitoring, rapid response to metric deviations, and configuration adjustments as production conditions reveal themselves — is managed by SmartDev rather than by the client’s internal team. Post-deployment monitoring runs continuously. Drift alerts are generated automatically. Configuration updates follow a documented change management process. The AI model maintenance and retraining cycle that keeps a production workflow performing reliably over time is included in the managed service rather than handed back to the client at go-live.
This matters for timeline because stabilization under a managed service model does not require the client to build the internal capability to manage it — which in most organizations takes longer than the stabilization period itself. The 6 to 8 week NORA deployment timeline reflects a working production system with active monitoring and managed stabilization, not a go-live date that marks the beginning of a separate internal stabilization effort.
If your organization has a pilot that has not made it to production, or is planning an AI workflow deployment and wants to understand what a realistic production path looks like for your specific context, contact SmartDev to discuss where the blockers are and what it would take to remove them.
Conclusion
The realistic pilot-to-production timeline for most enterprise AI deployments is not three months. It is six to eighteen months, with the variance almost entirely explained by non-technical factors — data readiness gaps discovered mid-build, stakeholder alignment failures at the production gate, absent governance infrastructure, and change management debt that prevents technically successful deployments from generating the business value they were designed to produce.
The organizations that compress this timeline are the ones that treat the foundational work — data readiness assessment, stakeholder engagement, governance setup, production path definition — as preconditions for the pilot rather than as follow-on work after it succeeds. That sequence is counterintuitive when organizational pressure is driving speed to demo. It is the only sequence that produces reliable speed to production.
Explore more from SmartDev:
Introduction: Compliance Is Becoming a Pattern-Recognition Problem
Fraud rarely announces itself. It usually hides inside thousands of small, unremarkable transactions. Each transaction looks fine on its own. But together, they form a suspicious pattern. This is why modern compliance is no longer just a checklist exercise. It has become a pattern-recognition problem at scale.
Compliance teams today face financial crime that is more organized than ever. Criminal networks adapt quickly. They know how to slip past static rules. Humans simply can’t process this volume of data alone. That’s where AI enters the picture.
The stakes are already massive. Financial institutions worldwide now spend more than $206 billion a year on financial crime compliance, according to LexisNexis Risk Solutions. Much of that cost comes from processing alerts, not catching criminals. It’s no surprise that 72% of compliance professionals already use analytics and AI to manage this workload, per the same LexisNexis study. For a broader look at where AI is already reshaping financial services, SmartDev’s overview of AI in finance is a useful starting point.
What AI Does Best: Detecting Patterns at Scale
AI doesn’t just flag “large transactions.” It learns what normal behavior looks like for each customer. Then it detects meaningful deviations from that baseline. For example, a customer who always transacts domestically suddenly starts sending money abroad. Each signal alone might seem minor. But layered together, they form a clear warning.
AI also excels at entity link analysis. Criminals rarely act alone. They often build shell companies, mule accounts, and crypto wallets to move money quietly. Link analysis tools can map these hidden relationships. They surface shared devices, matching IP addresses, or metadata tied to known bad actors.
On top of that, AI enables dynamic risk scoring. Instead of assigning a fixed risk label at onboarding, the system updates scores continuously. It factors in transaction volume, geography, and fresh external intelligence. As a result, teams act on current risk, not outdated profiles. The same logic is already speeding up onboarding itself – SmartDev’s piece on KYC document review automation shows how AI workflows now process onboarding packs in minutes instead of days.
Where AI Falls Short: Context, Intent, and Risk Interpretation
Still, AI has clear limits.
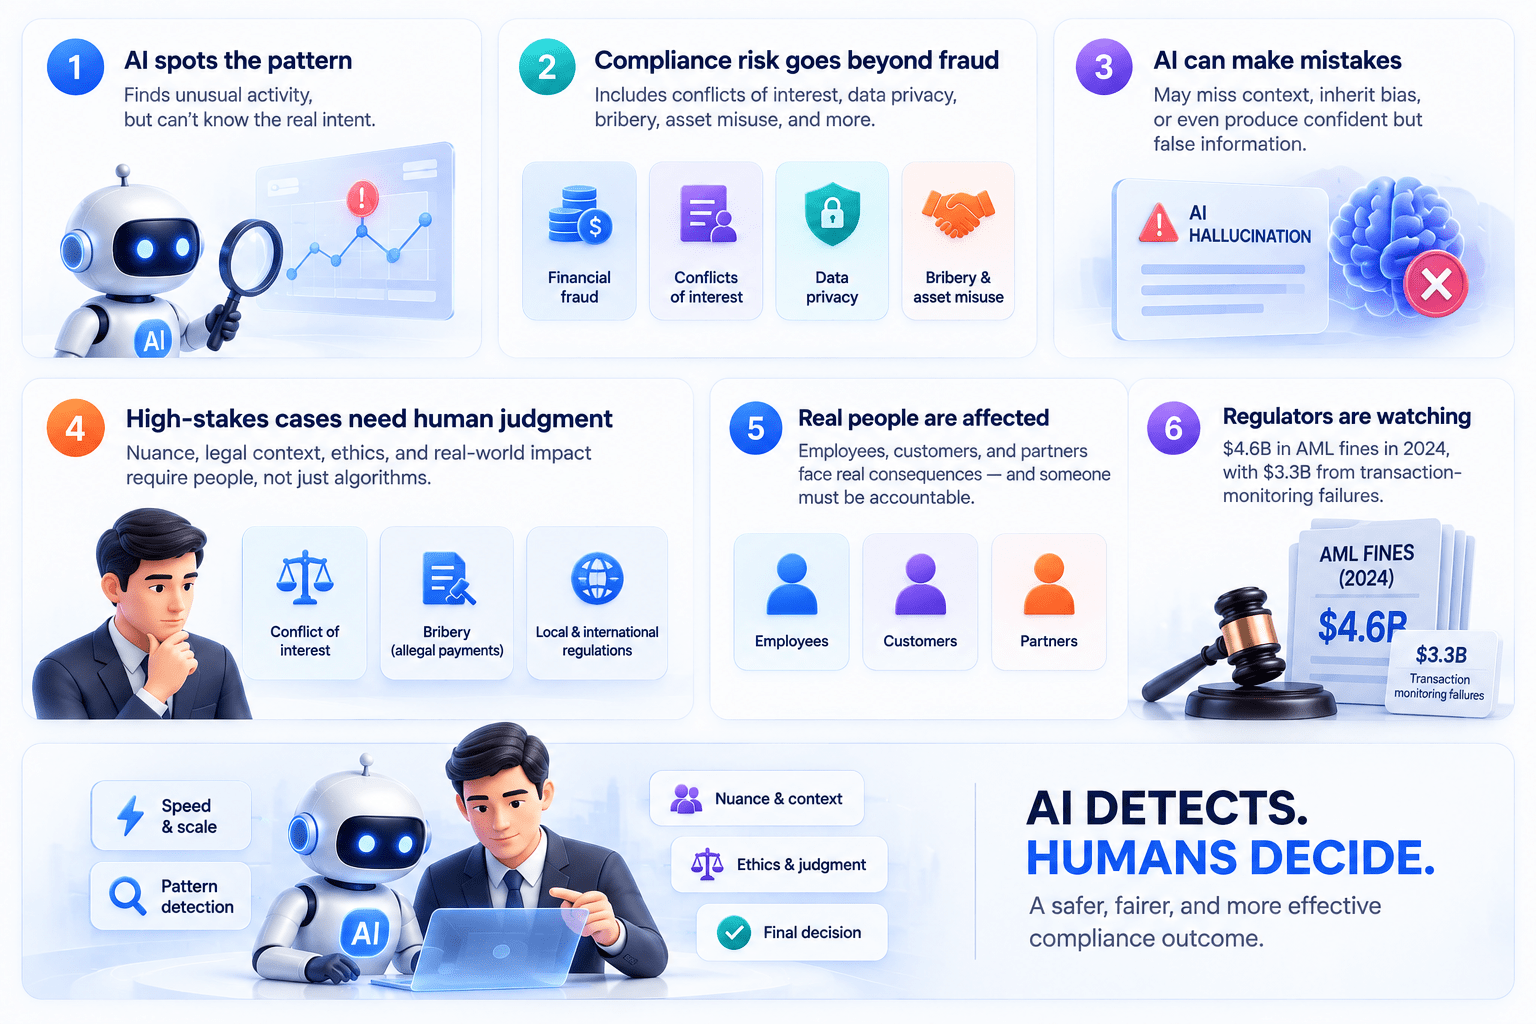
It can spot an unusual pattern. But it can’t truly understand why that pattern exists. An odd transaction might simply reflect a new job, a move, or a legitimate business expansion. AI lacks the ability to interpret real intent behind the numbers.
Compliance risk also extends far beyond financial fraud. It spans conflicts of interest, data privacy violations, bribery, and asset misuse. Each risk type demands a different kind of judgment and context. AI can flag unusual data. But classifying the true severity and legal weight of a case still requires human expertise.
Because of this, a system built purely on algorithms is prone to mistakes. It can miss important contextual factors. Worse, it can produce unfair outcomes if the training data carries hidden bias. SmartDev’s analysis of AI hallucination risk in compliance goes further: a model can state something false with total confidence, and in a compliance setting, that confidence can be more dangerous than an obvious error.
Why Human Judgment Still Matters in High-Stakes Compliance
In high-stakes situations, human judgment remains irreplaceable. Machines handle speed and volume well. But people understand nuance, ethics, and real-world consequences.
Take a conflict-of-interest report as an example. It needs evaluation within the organization’s specific culture. A bribery allegation requires knowledge of local and international law. These are judgment calls algorithms can’t yet make reliably.
Compliance decisions also affect real people directly. An employee might face investigation. A customer might lose access to a service. A partner might lose a contract. These outcomes demand clear accountability. A human has to make the final call.
The regulatory record backs this up. Global regulators issued $4.6 billion in AML-related enforcement actions in 2024 alone, according to Fenergo’s annual fines report. Of that total, $3.3 billion stemmed specifically from transaction-monitoring failures – cases where flagged activity wasn’t reviewed or escalated properly. A model that flags risk correctly still fails if no human closes the loop.
The Future Model: AI Detection + Human Decision-Making
Given all this, a practical model is emerging. It combines AI-driven detection with human decision-making. AI handles the heavy lifting of processing massive datasets. It surfaces the most suspicious signals from millions of transactions. Humans then review these prioritized alerts. They assess context, verify intent, and make the final call.
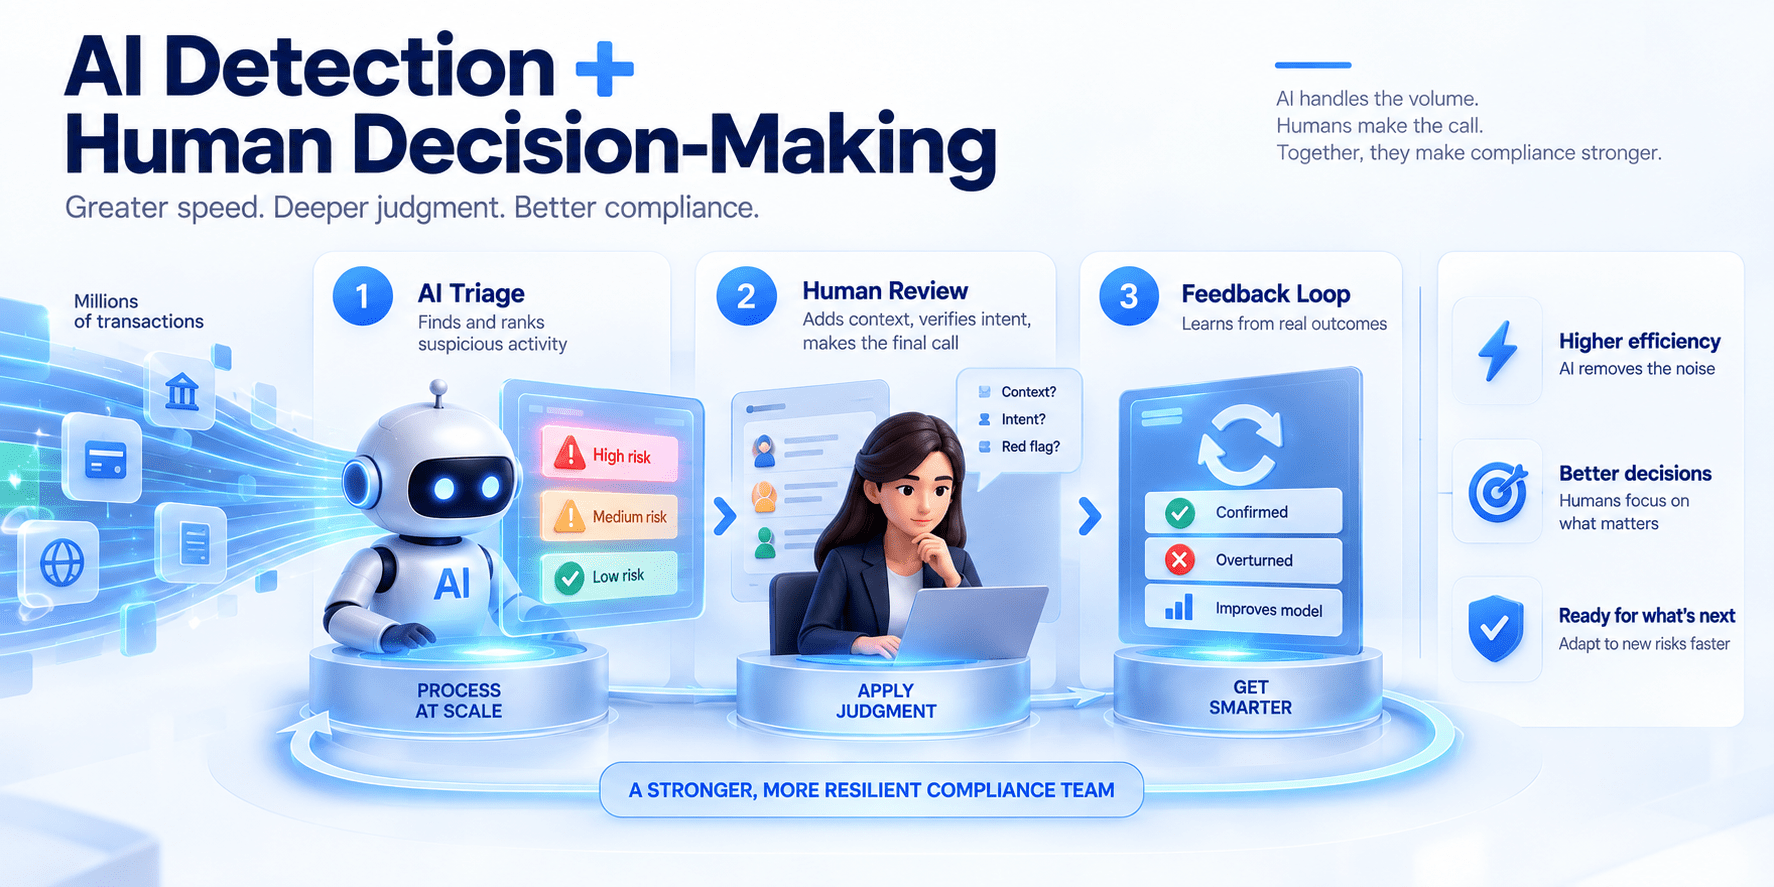
This model doesn’t treat AI as a replacement for people. It treats AI as an amplifier of human capability. By offloading repetitive, time-consuming work to AI, compliance experts can focus on genuinely complex cases. That balance between speed and accuracy is exactly what modern compliance needs. SmartDev calls this shift from processing alerts to making decisions, and its broader take on AI-native compliance for RegTech firms lays out what that shift looks like at an enterprise level.
In practice, this hybrid model usually runs on three layers. The first layer is automated triage. AI scores every transaction or report and sorts them by risk level, so nothing waits in an undifferentiated queue. The second layer is tiered escalation. Low-risk items get auto-cleared or logged for periodic sampling, medium-risk items go to junior analysts, and high-risk items go straight to senior investigators or legal counsel. The third layer is a feedback loop. Every human decision, whether it confirms or overturns an AI recommendation, feeds back into the model. Over time, the system learns from real outcomes instead of static rules.
This structure changes what a compliance analyst’s day actually looks like. Instead of scrolling through a flat list of thousands of alerts, an analyst opens a dashboard that already ranks cases by urgency and shows the evidence trail behind each score. They spend their time on judgment calls: is this pattern a coincidence, a red flag, or something in between? The model doesn’t remove complexity from compliance work. It removes the noise that used to bury the complexity.
The same structure also makes compliance teams more resilient to change. When a new typology emerges, such as a novel structuring technique or a fresh sanctions evasion route, the AI layer can be retrained relatively quickly on new labeled cases. Human reviewers, meanwhile, keep the institutional judgment needed to sanity-check the model’s new behavior before it goes live. Neither layer works well without the other; that interdependence is the actual point of the model, not a limitation of it.
Building Trust: Explainability, Accountability, and Auditability
For this hybrid model to work, trust is essential.
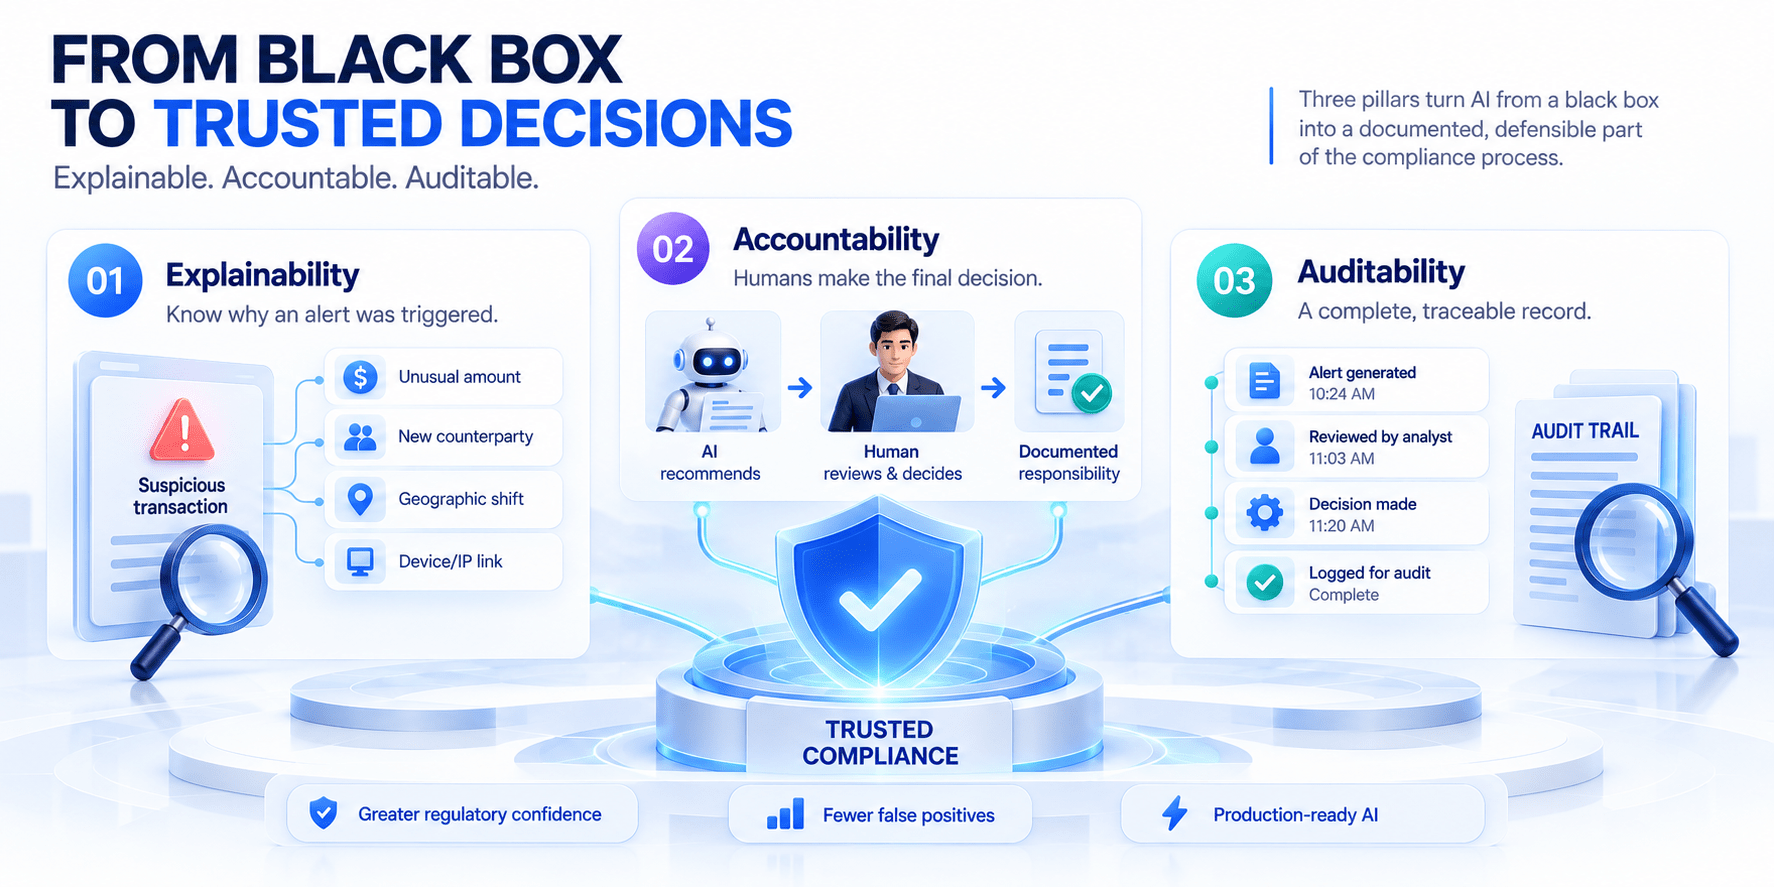
First, AI systems need clear explainability. When a transaction gets flagged, the compliance team needs to know exactly why. “The system triggered an alert” isn’t a good enough answer for a regulator. Explainability means the system can point to the specific factors behind a score: an unusual transfer amount, a new counterparty, a geographic shift, a device or IP link to a flagged account. Analysts can then confirm whether those factors genuinely apply to this case, or whether the model latched onto something coincidental. Without this layer, teams end up trusting a black box, which is a fragile position to defend in front of a regulator or in court.
Second, accountability must be clearly divided between machine and human. AI provides data and recommendations. But humans remain responsible for the final decision. This distinction matters most when regulators demand an explanation for a specific outcome. In practice, this usually means documenting who reviewed an alert, what evidence they considered, what the AI recommended, and why the final decision agreed with or diverged from that recommendation. That record is what turns “the AI decided” into “our compliance officer decided, informed by AI analysis” – a meaningfully different, and far more defensible, statement.
Third, every action in the system needs to be auditable. Each risk-score change and each generated alert should be logged in full. This allows the organization to prove its process is transparent and well-founded. A strong audit trail also does double duty internally: it lets compliance leaders spot patterns in false positives, measure analyst performance fairly, and demonstrate program maturity during internal reviews, not just external ones. SmartDev’s guides on building a compliance audit trail for AI-assisted decisions and how NORA makes every decision regulatorily defensible both dig into what that logging needs to look like in practice.
Together, these three pillars turn AI from a black box into a documented, defensible part of the compliance process. That distinction is often what separates a regulator’s approval from a regulator’s finding.
This is also precisely the gap that stalls most compliance AI initiatives today: a pilot that performs well in a demo but was never engineered for governed, audited production use. It’s a common enough problem that SmartDev is increasingly focused on closing exactly that gap – helping organizations take a working AI pilot and turn it into a safe, governed system that’s actually cleared to run in production. That same discipline runs through NORA’s AI workflow automation for risk and compliance, which by design routes low-confidence or flagged cases to human reviewers rather than letting the model make the final call alone.
From Alert Overload to Smarter Compliance Operations
One of the biggest problems in traditional compliance is alert overload. Tens of thousands of transactions get flagged every day. Only a small fraction actually deserve attention. This exhausts compliance teams and increases the risk of missing real threats.
The scale of this problem is well documented. Traditional AML systems generate a false positive rate as high as 90% to 95%, according to industry analysis from Datos Insights and Retail Banker International. Reviewing all that noise isn’t free -it’s part of why global AML compliance spending now exceeds $274 billion a year, with much of it going toward chasing low-quality alerts instead of real threats.
AI addresses this through contextual filtering. Instead of flagging every international transfer or every large payment, the system focuses on behavior that’s genuinely unusual for that specific customer. According to IDYC360’s analysis of AI-driven fraud detection, this kind of contextual filtering can cut alert volume by 40% to 60%. It frees up teams to focus on cases that truly matter. The gains aren’t just theoretical – SmartDev documented a case where workflow automation cut financial compliance review time by 80%.
Beyond filtering alerts, standardized risk categorization also helps enormously. When risk types like conflicts of interest, data security, and asset misuse are clearly classified, investigation and prioritization become faster and more accurate. NAVEX built its own risk taxonomy on 2.15 million whistleblower and incident reports received in 2024 – a dataset large enough to show that consistent categorization, not just faster detection, is what actually speeds up resolution. This is the foundation for shifting from reactive compliance to proactive risk management.
Conclusion: The Future of Compliance Is Augmented, Not Autonomous
In short, AI is reshaping how organizations approach compliance. It uncovers patterns that humans could never spot on their own. But it cannot fully replace human judgment in high-stakes decisions.
The future of compliance isn’t full automation. It’s mutual augmentation between machines and people. AI delivers scale and speed. Humans bring context, ethics, and accountability. When these two elements work together, organizations get a compliance system that’s both fast and trustworthy.
If your team already has a compliance AI pilot that works in a demo but hasn’t cleared production, that’s exactly the gap SmartDev helps close – turning a working pilot into a governed, audit-ready system. Talk to SmartDev about your next compliance AI pilot